| Decision area | What the evidence supports | Planning use |
|---|---|---|
| Complex nonlinear plants | PID performance is limited for complex nonlinear systems and real-time requirements. | Look at a learned component when tuning a PID loop no longer closes the performance gap. |
| Stability assurance | Learned models combined with model-based controllers can give precise control while proving theoretical stability bounds. | Prefer a hybrid design over a bare network when failure on hardware is costly. |
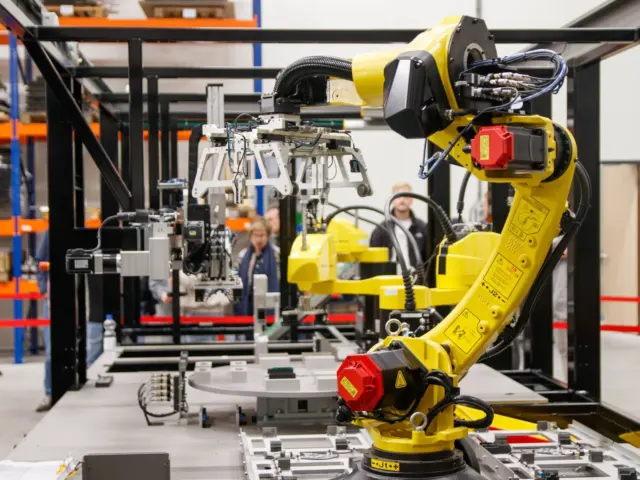
| Real hardware evidence | Physics-informed neural network models combined with model-based controllers were validated on trajectory tracking with a Franka Emika manipulator. | Use manipulator tracking as the reference case for a learned-plus-classical design. |
| Role inside joint control | Neural networks are analysed for inverse dynamics modelling, trajectory tracking control and adaptive control. | Decide whether the network replaces the loop or only models the plant inside it. |
The findings in this table come from a physics-informed control preprint on arXiv and a 2024 review of neural networks in robot joint control.
Neural network robot control means a learned function maps sensor readings to actuator commands. It suits complex nonlinear systems, but PID remains sound where it already performs well, and the real-time compute budget usually decides.
This page belongs to our wider coverage of artificial intelligence in robotics. It compares a learned policy with PID at the control-loop level: what changes in the loop, what it costs at run time, and how it can fail.
What a learned controller changes in practice
A learned controller changes three things at once: how much plant behaviour you must model by hand, how much computation sits inside every control cycle, and how much you can prove about stability. The gains show up on hard plants. The costs show up on the robot’s computer.
Nonlinear plants and coupled joints
A PID controller reacts to error with a fixed feedback structure. A 2024 review of neural networks in robot joint control notes that PID performs well in some applications but is limited for complex nonlinear systems and real-time requirements. A neural network can absorb nonlinear behaviour that a fixed gain structure handles poorly, because it learns the mapping from data instead of from a hand-derived equation.
That advantage grows with the number of interacting joints. A multi-limbed robot has joints whose motions affect each other, and a single learned policy can command them together instead of treating each joint as an isolated loop.
Stability you can still argue for
The main objection to a network in the loop is that its behaviour is hard to bound. The arXiv preprint on physics-informed control shows a way around this. By combining learned models with model-based controllers, the authors report precise control performance while proving theoretical stability bounds. The preprint’s validation used trajectory tracking on a Franka Emika manipulator, a real arm rather than a simulation.
The practical lesson is architectural. Keep a structured controller responsible for stability, and let the network improve the model it relies on.
Compute cost inside the loop
The cost side is documented in a master’s thesis repository on event-based end-to-end robot control. It describes deep neural network controllers as computationally expensive and particularly problematic in real-time applications and on mobile devices such as autonomous robots. A PID update is a few arithmetic operations. A deep network evaluation is far heavier, and that difference sets the ceiling on how fast the loop can run.
Choosing between PID, MPC and a learned policy
The right choice depends on how hard the plant is to model, how tight the timing is and how much assurance the application needs. Treat the options as a ladder: move up only when the simpler controller has demonstrably run out of performance.
- Stay with PID when the loop already meets its performance target. The review above says PID performs well in some applications, and a controller you can tune and reason about by hand is an asset on a small mobile robot with limited compute.
- Use model predictive control when you have a usable plant model and want constraints handled explicitly. It is a model-based approach, so its behaviour traces back to the model you supplied. The same review lists integrating deep learning with reinforcement learning and MPC as a future challenge for neural robot control, which signals that hybrids are still maturing.
- Add a learned model to a classical controller when the plant is nonlinear but stability bounds matter. This is the pattern in the Franka Emika preprint, where learned models support a model-based controller.
- Deploy a learned control policy directly when the plant is too complex to model well, you can afford the inference cost in every cycle, and a safe fallback exists.
The deciding question is not whether a network can control the robot. It is whether the improvement over a well-tuned classical loop justifies the extra compute and the weaker guarantees.
Loop rate, latency and stability
A controller keeps a robot stable only if it delivers a fresh command before the plant has drifted too far from the state the command was computed for. Rate and latency are therefore properties of the whole sense, compute and actuate path, not of the network alone.
The supplied evidence gives no universal figure for the required rate, and none should be assumed. The thesis repository shows why: deep network controllers are expensive enough to be problematic in real-time use and on mobile robots. The rate you need follows from your robot’s dynamics, and the rate you can sustain follows from the network size and the onboard processor.
Use these principles when sizing the loop:
- Budget the full path. Count sensor read, preprocessing, network inference and actuator write together, because latency anywhere erodes stability margin.
- Shrink the network before raising the clock. A smaller policy that fits the cycle is safer than a larger one that occasionally misses it.
- Keep a fast inner loop classical. If a PID or model-based loop runs at the actuator, a slower learned layer can supply targets above it. This reflects the hybrid pattern the preprint validated, though that work does not prescribe layer rates.
Localization sits in the same timing chain. A policy is only as good as its state input, so robot localization algorithms belong in the latency budget as well.
How learned policies are trained and deployed
A learned control policy is usually trained by reinforcement learning, where the controller improves through trial and reward, or by supervised learning from examples. The two can be chained. The thesis repository describes a policy learned with the DQN reinforcement learning algorithm and then transferred to a spiking network using supervised learning.
That work is a simulated lane-following task built with V-REP and ROS. It is a useful illustration of the pipeline and of a compute-saving idea, since spiking networks are aimed at the cost problem described above. It is not evidence of performance on physical hardware.
Hardware evidence comes from the Franka Emika manipulator work, where learned physics-informed models were combined with model-based control and validated on trajectory tracking. The review adds the wider set of roles that networks play in joint control: inverse dynamics modelling, trajectory tracking control and adaptive control.
Moving from training to the robot means freezing the trained network, running it on the onboard computer inside the control cycle, and checking that its timing and behaviour match what training assumed. Differences between a simulator and the real robot are the main risk at that step, and sim to real transfer robotics covers how that gap is handled.
What can go wrong on physical hardware
Failures on hardware come from the mismatch between what the network learned and what the robot does, plus the constraints of running it in real time. Plan for these before the first powered test.
- Missed deadlines. Deep networks are computationally expensive, and the thesis repository flags real-time and mobile use as particularly problematic. A late command acts on stale state.
- No stability argument. A network alone offers no proof of bounded behaviour. The stability bounds in the arXiv preprint come from pairing learned models with a model-based controller.
- Simulation-only evidence. A policy shown to work in simulation, as in the lane-following study, has not yet demonstrated that it works on the robot. Treat first hardware runs as validation, with limited speed and torque.
- Unbounded outputs. A learned policy can emit commands outside what the actuators or the surroundings tolerate. Put a conventional supervisor or limiter between the network and the motors.
A sensible deployment keeps a classical controller as the fallback and lets the learned component earn trust in stages.
Frequently asked questions
Is a neural network always better than PID for a robot?
No. PID performs well in some applications, and its limits show mainly on complex nonlinear systems and demanding real-time requirements. Where a tuned PID loop meets its target, a network adds compute cost without a clear gain.
Can a learned controller come with stability guarantees?
It can when combined with a model-based controller. The Franka Emika preprint reports precise control together with theoretical stability bounds, though the extract gives no numeric bound.
What role does reinforcement learning play?
It is a training method for producing the policy. In the thesis example, a policy learned with DQN was then transferred to a spiking network by supervised learning, in a simulated task.
Which controllers are expected to be combined with neural networks next?
The 2024 review points to integrating deep learning with reinforcement learning and model predictive control as the main future challenge for neural robot control.